Logs explain events
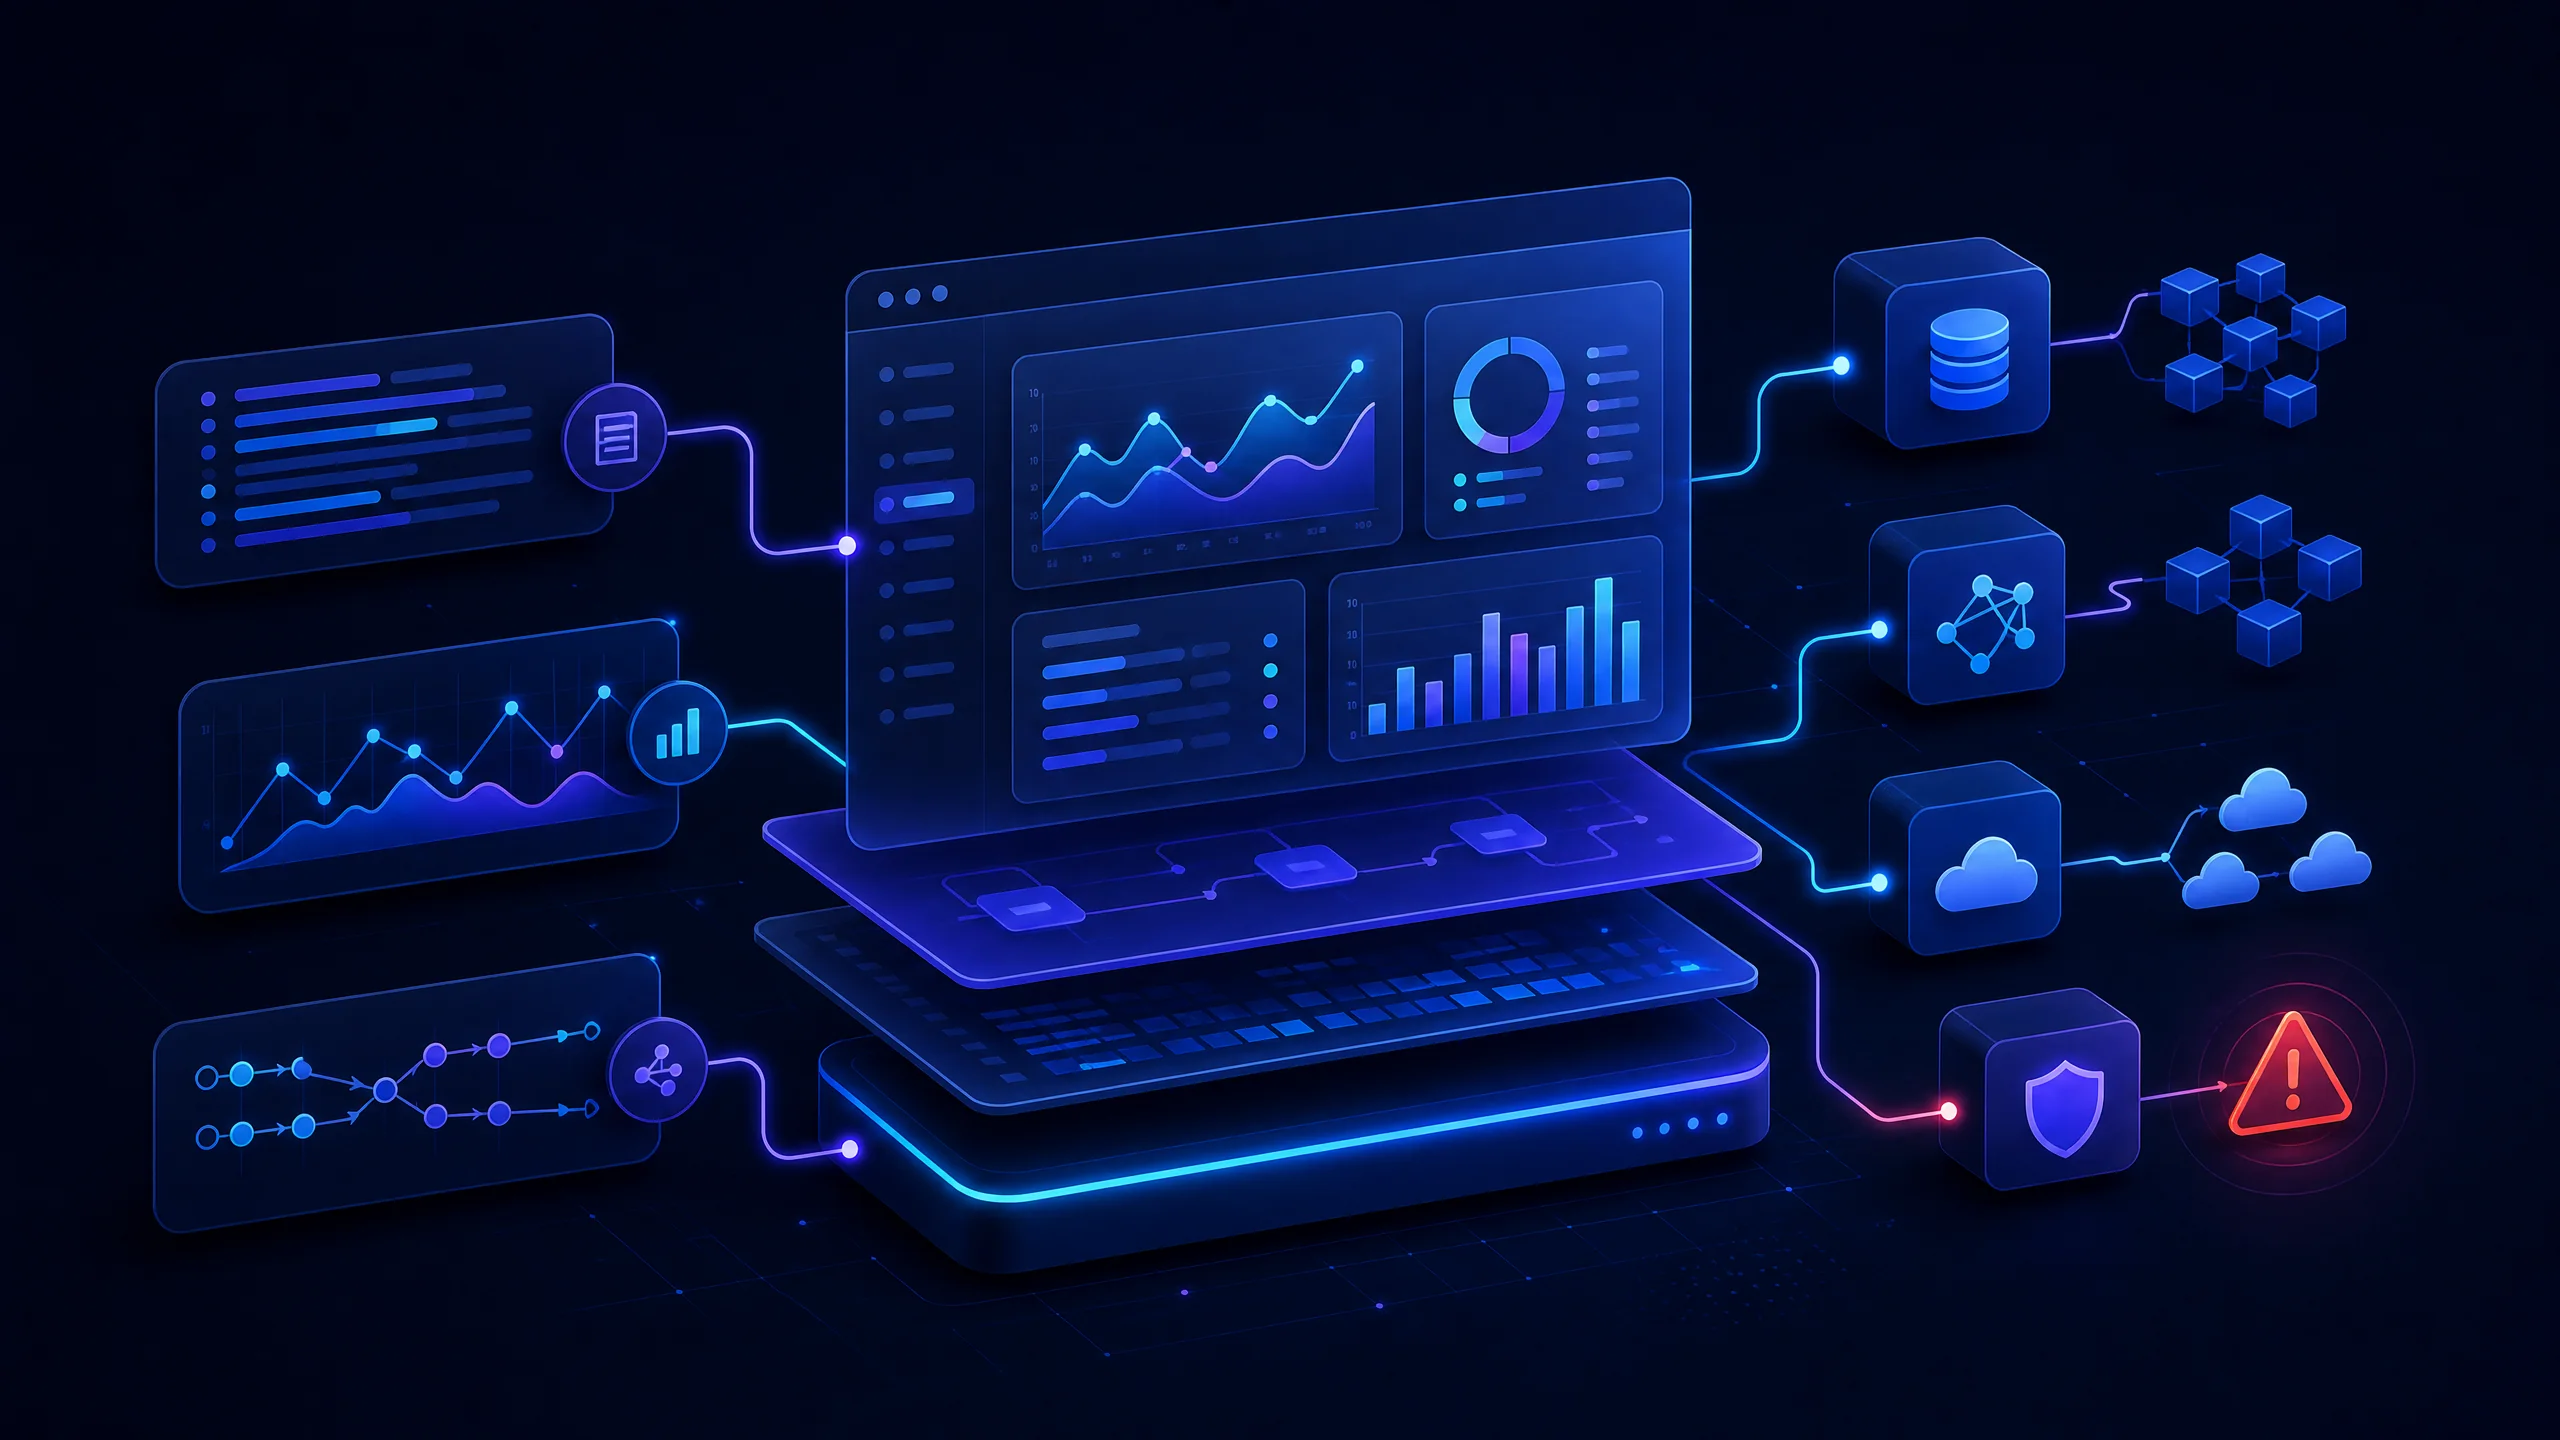
Structured logs should answer what happened, where it happened, and which request or user was involved. Include a correlation ID, but avoid writing passwords, tokens, or unnecessary personal data.
Metrics reveal patterns
Track request rate, error rate, latency percentiles, queue depth, database pool usage, and resource saturation. Percentiles are more informative than an average when a small group of users experiences very slow requests.
Traces connect the path
A trace can show that a slow page came from an API call, which waited on a database query, which in turn waited on a remote service. This context shortens diagnosis time dramatically.
Define an actionable alert
Alert on symptoms that need a human response, not every exception. Each alert should have an owner, a runbook, and a clear definition of when the incident is resolved.